Task/PoC agent
from $2,900
2–3 weeks · single-task / proof
A single-task agent or a runnable proof of concept: one workflow, tool inventory and the honest agent-vs-pipeline decision before you commit to a build.
Get a quoteProduction AI agents built by engineers who have shipped them — not by teams who learned the word last quarter. We map use cases to the agent-vs-pipeline decision honestly, design tool orchestration that survives at 2am, build memory tiers that do not balloon your OpenAI bill, and ship human-in-the-loop checkpoints on every irreversible action. Fixed-scope, all-in USD pricing, tiered by autonomy: a task or PoC agent from $2,900, a RAG-grounded agent from $8,100, an autonomous agent from $10,400, and a multi-agent or ML-in-production system up to $13,800. IP transferred on day one, no recruitment markup, no tool surcharges.
GDPR-aligned · ISO 27001 ready · SOC 2 Type II in progress · HIPAA-capable · CCPA-acknowledged · CET workday with 9 AM–1 PM ET overlap
Most agent projects fail because the problem did not need an agent. A deterministic pipeline plus one LLM call would have shipped in three weeks and run for a tenth the cost. We say so in the feasibility sprint. When you do need an agent — multi-step workflows over changing state, tool sequences that cannot be hardcoded, verifiable success criteria — we build them the way they survive production: explicit graphs, validated tool calls, hard token budgets, tiered human-in-the-loop, and observability that captures every step. The agent that runs your refunds queue cannot loop 40 times into your Stripe bill at 3am and discover it on Monday.
We score candidate workflows on the three agent prerequisites — non-deterministic tool order, evolving state, verifiable success — and we explicitly call out the ones where a pipeline plus one LLM call would ship faster and cheaper.
Tool definitions with strict Pydantic schemas, retry and back-off per tool, idempotency keys on writes, and an explicit graph so the control flow is debuggable instead of emergent. LangGraph, Temporal, or Inngest depending on durability needs.
When the workload genuinely benefits from specialist agents (rare), we design supervisor and worker patterns with clear hand-off contracts. When it does not, we save you the complexity and ship a single-agent system that you can actually operate.
Short-term conversation buffer with summarisation, long-term episodic memory in pgvector or Weaviate, semantic RAG for the underlying corpus. Each tier sized explicitly so memory cost stays at 30 to 60 percent of LLM cost, not 300.
Tiered approvals: autonomous for reads, async-revert for medium-risk writes, sync-approval for irreversible actions (email, production, payments). Approval UIs are part of the deliverable — Slack interactive messages, your admin, or a custom inbox.
Per-task token and dollar budgets enforced at the orchestrator. Step-level traces in Langfuse, Helicone, or Arize. Cost alerts wired to PagerDuty, not dashboards you check on Monday. Eval harness running in CI on every prompt change.
 LangGraphAI / ML
 Anthropic Tool UseAI / ML
 Vercel AI SDKCloud
 TemporalMessaging / streaming
 PhoenixBackend
 PosthogObservability
 pgvectorVector DBWeaviateVector DBClaude 3.7 SonnetAI / ML
Weeks 1–2: use-case mapping, agent-vs-pipeline decision, tool inventory across your existing APIs, ROI model. Output is a written go/no-go with the cheaper alternative scoped if go is no.
Weeks 3–4: orchestrator chosen (LangGraph vs Temporal vs Inngest based on durability), tool schemas in Pydantic, memory tiers sized, checkpoint tiers assigned per tool, ADRs written.
Weeks 5–9: agent built, tool integrations live, human-in-the-loop UI shipped, observability wired, eval harness running in CI, customer-zero deployment behind a feature flag with hard budget caps.
Week 10+: gradual traffic ramp, cost and latency SLOs, runbook for stuck agents and tool outages, your team trained on adding tools and expanding the eval set. We step out when your team is operating it.
2–3 weeks. A single-task agent or a runnable proof of concept: one workflow, tool inventory, a scoped agent-vs-pipeline decision. Best when you need to prove the idea before a build. From $2,900 fixed.
4–6 weeks. Retrieval and grounding over your corpus: ingestion and chunking, a vector store, grounded answers with citations, an eval harness. From $8,100 fixed.
6–9 weeks. Tool orchestration, memory tiers, tiered human-in-the-loop checkpoints and observability with hard per-task budgets, shipped to production behind a feature flag. From $10,400 fixed.
9–13 weeks. A multi-agent system or an ML pipeline running in production: supervisor/worker patterns or model serving, monitoring and cost controls. From $13,800 fixed.
All engagements start with a mutual NDA, IP assignment on day one, and a DPA. You see the line-item budget at the end of discovery and sign off before any code is written — no recruitment markup, no tool surcharges.
Fixed-scope, all-in USD pricing so you can budget before discovery. Every agent is scoped individually, but these four tiers cover the common paths from a single-task proof of concept to a multi-agent or ML system running in production. You see the line-item budget at the end of discovery and sign off before any code is written — no recruitment markup, no tool surcharges.
Task/PoC agent
from $2,900
2–3 weeks · single-task / proof
A single-task agent or a runnable proof of concept: one workflow, tool inventory and the honest agent-vs-pipeline decision before you commit to a build.
Get a quoteRAG-grounded agent
from $8,100
4–6 weeks · retrieval + grounding
Retrieval and grounding over your corpus: ingestion and chunking, a vector store, grounded answers with citations and an eval harness that catches regressions.
Get a quoteAutonomous AI agent
from $10,400
6–9 weeks · orchestration + HITL
Tool orchestration, memory tiers, tiered human-in-the-loop checkpoints and observability with hard per-task cost budgets, shipped to production behind a feature flag.
Get a quoteMulti-agent / ML in prod
from $13,800
9–13 weeks · multi-agent / ML pipeline
A multi-agent system or an ML pipeline running in production: supervisor/worker patterns or model serving, monitoring, cost controls and a handover your team can operate.
Get a quoteWhat moves the number: how many tools the agent orchestrates and how non-deterministic their order is; how many memory tiers it needs (buffer, episodic, semantic RAG); the depth of human-in-the-loop checkpoints on irreversible actions; and compliance scope (GDPR-aligned, HIPAA-capable, or PCI DSS work raises the bar). You see the line-item budget at the end of discovery and sign off before any code is written — no recruitment markup, no tool surcharges. Cloud fees run on your own accounts, so you keep the cost lever.
Agents spend tokens on every step: the system prompt, tool schemas and history are resent each turn. Measure a real prompt in our free token counter, then project the monthly bill in the LLM Spend Calculator.
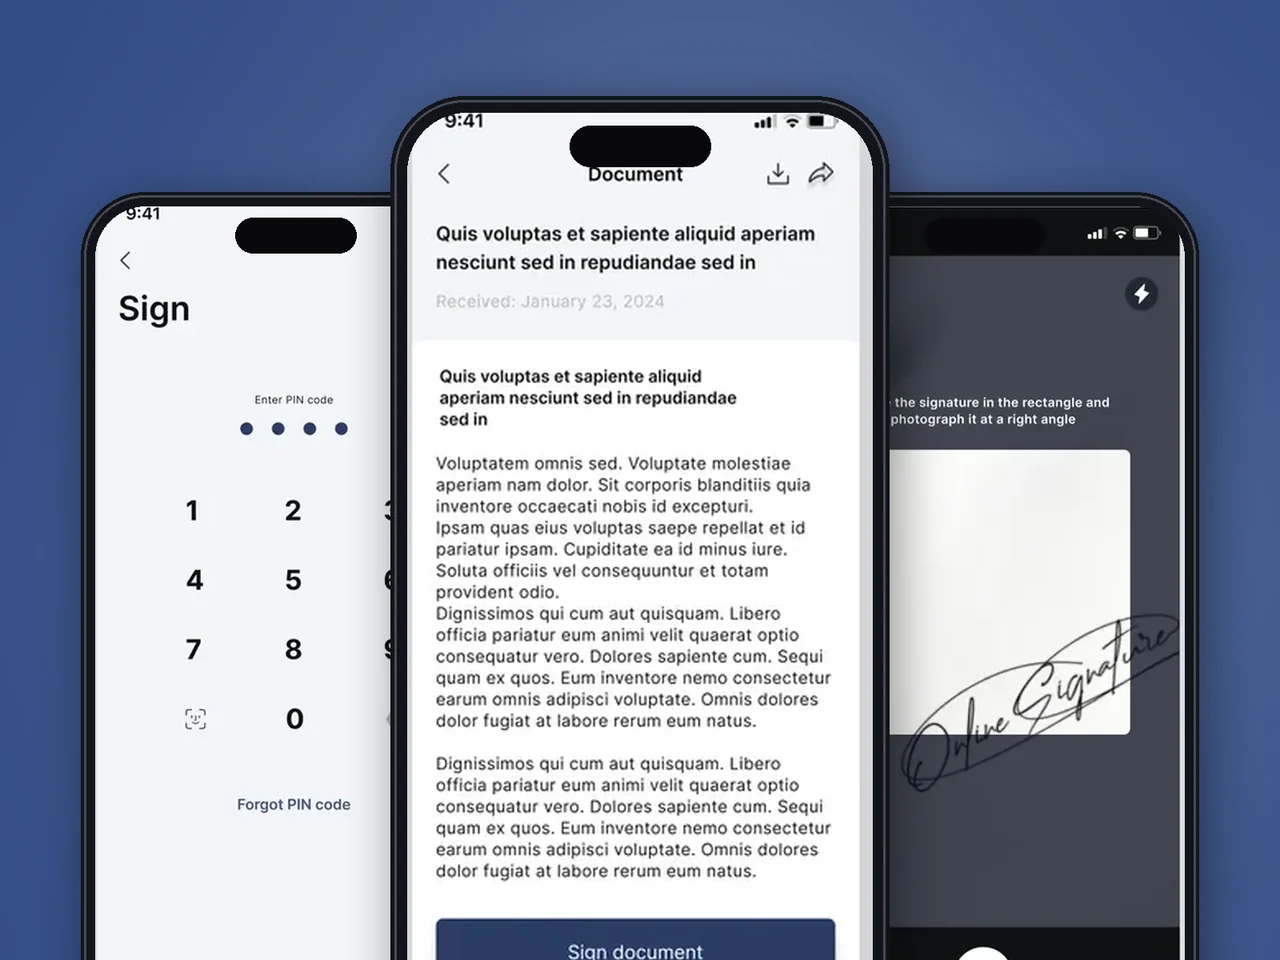
Native iOS and Android e-signature clients with a Symfony + React CRM for a cross-border law firm — KYC onboarding and a defensible evidence trail for US & EU matters.
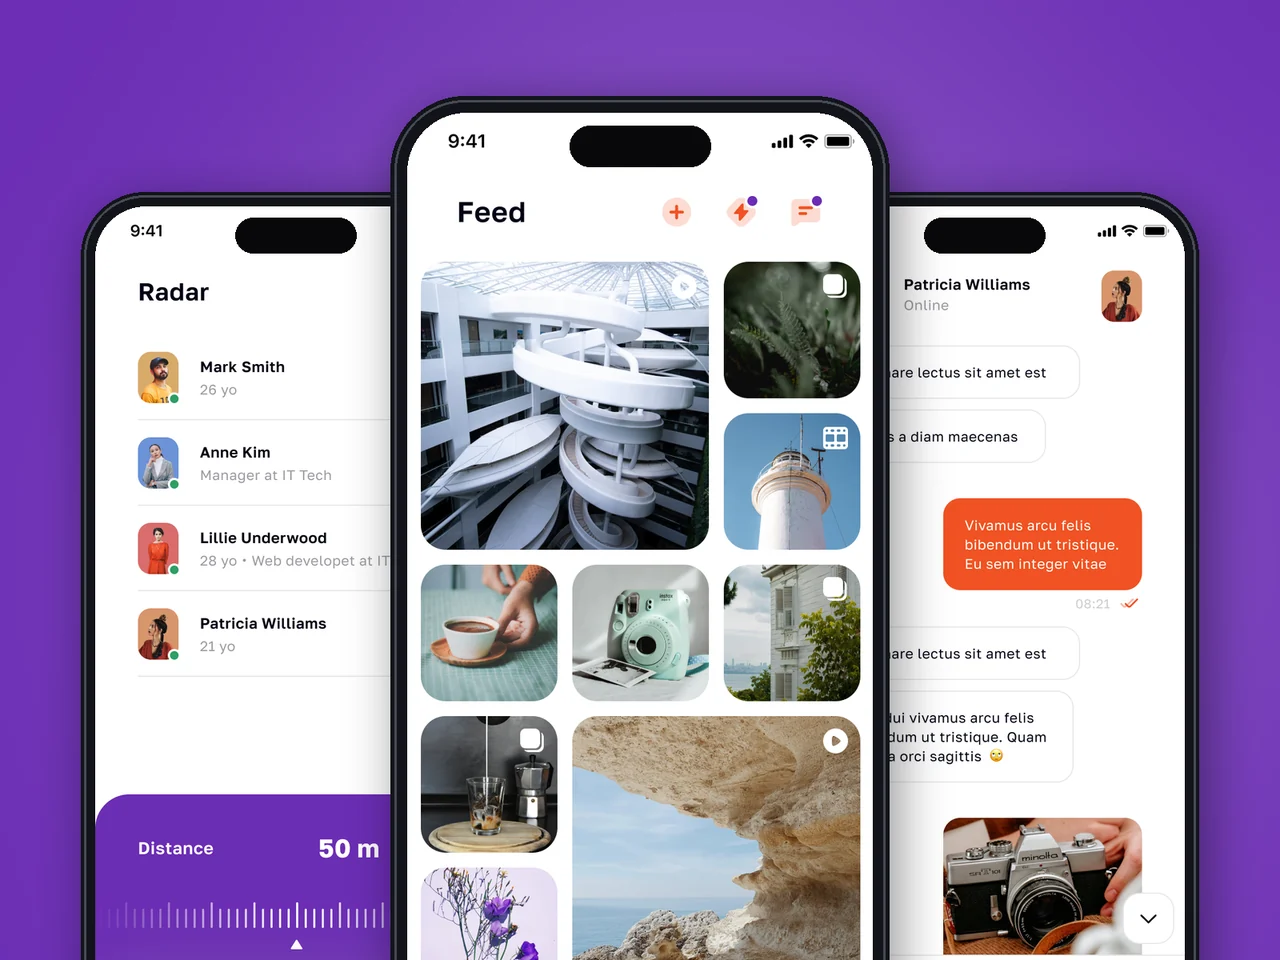
Production social platform — App Store + Google Play, live across the US and EU — with geo Radar, encrypted messaging and a virtual economy.
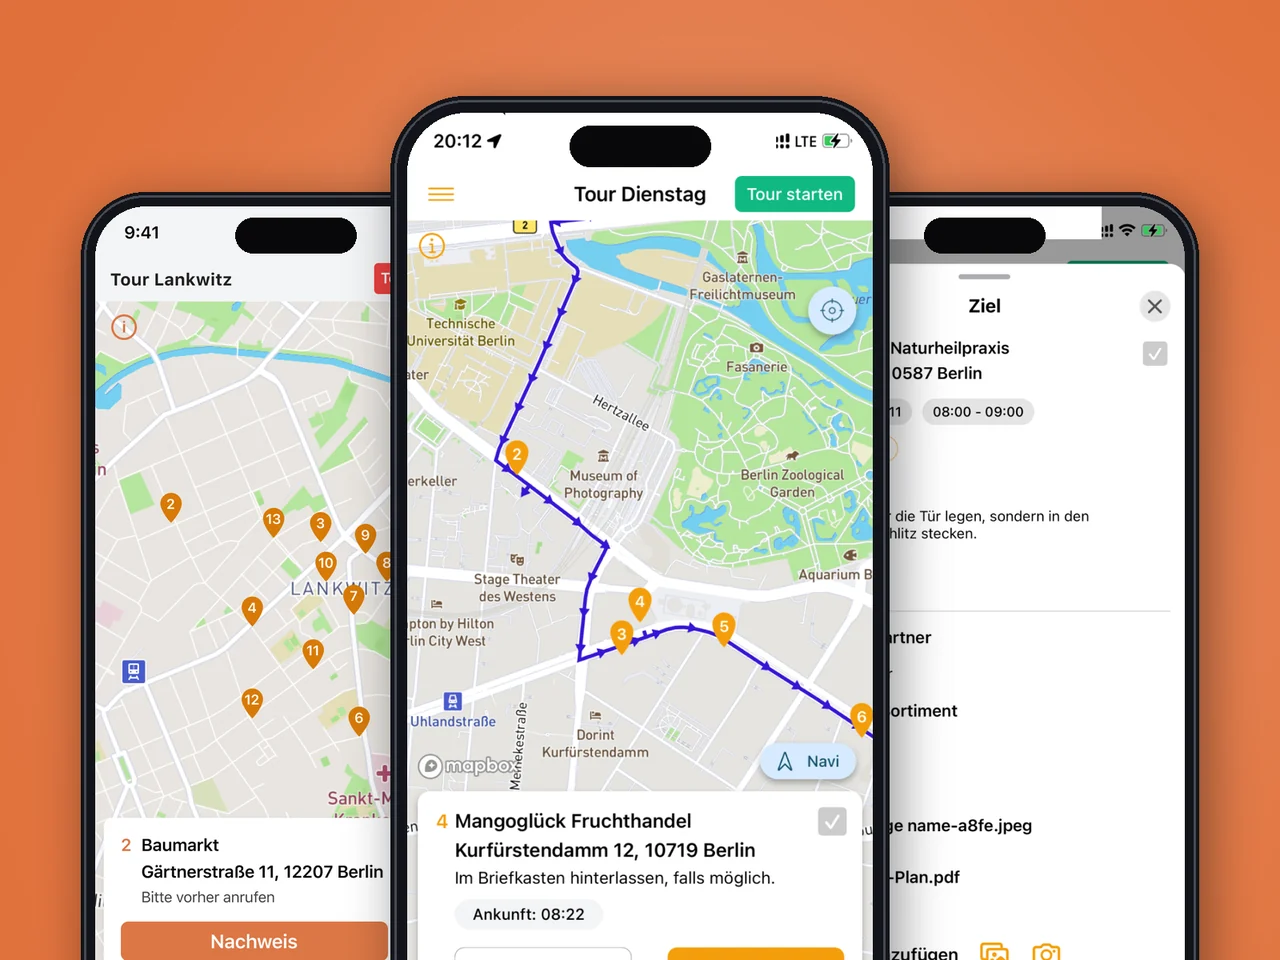
Android + iOS refactor and rebuild for a German last-mile logistics operator — multi-point route planning, real-time driver tracking and in-app invoicing live in the EU.
An agent is only as safe as its fit with your regulatory and operational reality. We pair agent engineering with industry-specific compliance across US & EU markets, and pull in our sibling AI, ML & data, GenAI integration and EU AI Act compliance teams when a workload needs them.
Agents for reconciliation, dispute triage and underwriting support with human-in-the-loop on every irreversible action and PCI DSS-scope data handling.
HIPAA-capable, GDPR-aligned agents for intake, records retrieval and care-ops workflows — with documented data flows and sync-approval gates on clinical actions.
Agents for order operations, catalogue enrichment and support triage that call your existing APIs under strict tool schemas and hard per-task budgets.
Agents for exception handling, route and ETA queries and back-office automation over changing state — durable workflows on Temporal or Inngest when steps must survive restarts.
Agents for contract review, clause extraction and matter intake grounded in your document set — answers cite the source paragraph, and sync-approval gates fire before anything leaves the firm.
Agents for first-notice-of-loss triage, claims routing and policy Q&A over changing state, with hard per-task budgets and human approval on any payout or coverage decision.
An agent is only useful if it can reach your systems safely. We wrap each integration in a strict tool schema with retries, idempotency keys on writes and a per-tool checkpoint tier, so the agent calls your stack the way a careful engineer would — not the way a loose script does at 3am.
Slack, Microsoft Teams, email and ticketing (Zendesk, Intercom, Jira) as both the agent's input surface and its human-in-the-loop approval UI — interactive messages, queued actions and approval inboxes rather than a separate tool no one opens.
Salesforce, HubSpot, Stripe, NetSuite and your internal admin APIs, called under strict tool schemas with idempotency on every write, so a retried action never double-charges a card or double-posts an order.
PostgreSQL and pgvector, Weaviate, Snowflake and object storage back the RAG corpus and episodic memory, with ingestion and chunking pipelines that keep retrieval grounded, current and cited.
OpenAI, Anthropic and Google models behind a provider-agnostic layer, so you route by cost and capability per step and swap models without rewriting the agent or re-running your whole eval set from scratch.
Temporal and Inngest when a run must survive restarts, retries and multi-hour waits — the agent becomes a durable workflow with LLM steps inside, not a process that dies on a timeout and loses its place.
Langfuse, Helicone and Arize for step-level traces, plus cost and latency alerts wired to PagerDuty and your existing on-call — so a runaway agent pages someone at once, not on Monday morning.
GDPR-aligned · ISO 27001 ready · SOC 2 Type II in progress · HIPAA-capable · CCPA-acknowledged
We have killed more agent projects than we have shipped. When a pipeline plus one LLM call wins on cost and reliability, we say so — even though it shrinks our scope. The MVPs we do ship survive production.
Our agent leads have run durable workflows on Temporal and Inngest before agents existed. They know what an orphaned task looks like in a queue at 3am, and they design checkpoints accordingly.
Hard token and dollar budgets at the orchestrator from day one. Memory tiers sized to keep cost predictable. Agents that cap themselves before they cap your finance team.
We treat agents as production systems with non-deterministic control flow — not as chatbots that happen to call APIs. The discipline difference is the difference between an agent that runs your refunds queue and one that costs you a Monday-morning incident review.
A loan decision engine that takes ten times less time to approve does not happen by accident. YuSMP built the scoring pipeline, integration with credit bureaus, and a back-office that our underwriters actually enjoy using. Approval turnaround went from two days to under four hours.
We publish dozens of sports articles a day. YuSMP built an editorial pipeline using a Telegram bot as the CMS — editors post once, content lands on web, iOS, and Android instantly. The architecture requires zero daily maintenance.
1 / 2
Default to a single LLM call. Move to an agent only when the task has three properties: it requires multiple tool calls whose order cannot be hardcoded, it operates over state that changes across turns, and the success criterion is verifiable enough that the agent can self-correct. Customer support triage is rarely an agent; ops workflows that touch four internal APIs in a different order each time often are. We refuse agent projects where a deterministic pipeline plus one LLM call would ship in half the time with a quarter of the bugs.
Depends on the workload. LangGraph for stateful agents with branching control flow and human checkpoints — the explicit graph is worth its weight when you debug at 2am. CrewAI or AutoGen when multi-agent collaboration is the actual pattern (rare). OpenAI Assistants when the workload is tightly coupled to OpenAI's tool format and you do not need portability. Temporal or Inngest when the agent is really a durable workflow with LLM steps inside. Vercel AI SDK for Next.js front-ends with simple tool use. We pick on operational fit, not vendor preference.
Three controls. Hard per-task token and dollar budgets at the orchestration layer — the agent terminates with a clear error before it loops 40 times into your OpenAI bill. Step-level tool-call validation through Pydantic so invalid arguments are caught before the API call, not after. Human-in-the-loop checkpoints on irreversible actions (sending email, posting to production, charging a card). Observability through Langfuse, Helicone, or Arize logs every step, every tool call, every token. Cost alerts fire on the orchestrator, not the dashboard you check on Monday.
Memory is three things, not one. Short-term: the current conversation buffer, summarised when it exceeds context budget. Long-term episodic: facts the agent learned about the user or task, stored in a vector store with semantic recall (pgvector or Weaviate). Long-term semantic: the corpus the agent retrieves from, treated as a RAG subsystem. We size each tier explicitly because naively cramming everything into the context window costs five to ten times more per request and degrades quality. Per-agent memory cost is typically 30 to 60 percent of the LLM cost when designed; 300 percent when not.
Tiered checkpoints. Tier 1 (autonomous): read-only actions, no human gate. Tier 2 (async review): a human sees and can revert within a window, but the agent does not block. Tier 3 (sync approval): irreversible actions (sending email, posting to production, charging) wait on human approval before execution. The approval UI is part of the deliverable, not an afterthought — usually a Slack interactive message, a queued action in your existing admin, or a custom approval inbox. Tier assignment is per tool, written down, and changes through PRs not Slack.
Four fixed-scope tiers, all-in and quoted in USD. A task/PoC agent runs from $2,900 (2–3 weeks): a single-task agent or a working proof of concept. A RAG-grounded agent from $8,100 (4–6 weeks): retrieval and grounding over your corpus with citations. An autonomous AI agent from $10,400 (6–9 weeks): tool orchestration, memory, human-in-the-loop and observability. A multi-agent or ML-in-production system from $13,800 (9–13 weeks). You see the line-item budget at the end of discovery and sign off before any code is written. No recruitment markup, no tool surcharges; cloud fees run on your own accounts, so you keep the cost lever.
You do, from day one. IP assignment is signed before the build starts, so the code, the prompt library, the eval set, the tool schemas and the orchestration config are all yours. We hand over the repository, the infrastructure-as-code and the runbooks; there is no proprietary runtime you have to keep licensing from us to keep the agent alive. Cloud and model accounts are yours too, which is why you keep the cost lever rather than paying a marked-up passthrough.
Yes. The provider layer is deliberately model-agnostic, so if you are standardised on Azure OpenAI, Anthropic on Bedrock, or Google Vertex for contractual or residency reasons, the agent routes through it without a rewrite. For GDPR-aligned work we keep the data plane in your chosen region, document every place data crosses a boundary, strip or tokenise PII before it reaches a model where that is required, and can run retrieval and memory entirely inside your VPC. Compliance scope (GDPR, HIPAA-capable, PCI DSS) is priced in, not bolted on.
Every engagement past the PoC tier ships an eval harness, and it runs in CI on each prompt or tool change — not as a one-off demo. We build a graded test set from real tasks, score correctness, tool-call validity, groundedness (for RAG) and cost per task, and gate deploys on regressions. Production rollout is a gradual traffic ramp behind a feature flag with cost and latency SLOs, so the first real users are a controlled slice, not the whole queue. An agent that cannot be measured is an agent we will not put in front of your customers.
Often, yes. We start with a short audit: where control flow is emergent instead of explicit, where tool calls lack validation or idempotency, where cost runs away, and whether memory is cramming everything into the context window. You get a written findings list with the honest call — refactor the existing graph, or rebuild the risky parts. Many rescues are less about the model and more about the missing operational scaffolding: budgets, checkpoints, traces and evals that were never there.
Defence in depth, because no single control is enough. Tool arguments are validated through strict Pydantic schemas before any API call, so a manipulated instruction cannot smuggle a malformed or out-of-scope action through. Irreversible tools sit behind sync-approval checkpoints regardless of what the model “decided”. Retrieved and user-supplied content is treated as untrusted data, not as instructions, and kept out of the privileged system prompt. Least-privilege credentials mean a compromised step cannot reach systems it was never scoped for, and every step is traced so misuse is visible after the fact.
That is the goal of the rollout phase, not an afterthought. You get the repository, infrastructure-as-code, the eval set, observability dashboards and a runbook covering stuck agents, tool outages and cost spikes. We train your engineers on adding tools, expanding the eval set and reading the traces, then step out when your team is operating the agent day to day. If you want ongoing help, support is a separate agreement with a defined SLA — a choice, not a dependency we engineer in.
Tell us where you want to be in twelve months. We’ll come back with a plan to get you there.
Practical guides on AI agents and LLM orchestration for US & EU product teams.
Share a few details and a senior consultant will reply within one business day.
Email: sales@yusmpgroup.com
Phone: +374 44 871 811
Offices: KAMAR Business Center, Vazgen Sargsyan St. 2, Yerevan, Armenia · Remote — East-Coast US overlap (9 AM–1 PM ET)