Collection & index configuration
Choosing the right vector size, distance metric and HNSW parameters (m, ef_construct, ef) up front, since poor index config quietly caps recall and latency later.
We design, tune and run Qdrant as the retrieval engine behind production RAG, semantic search and recommendation systems. For US teams we self-host inside your VPC for HIPAA and SOC 2 control; for EU clients we keep vectors and payloads in-region for GDPR data residency. From collection schema to distributed sharding, we own the whole vector layer.
We design, tune and run Qdrant as the retrieval engine behind production RAG, semantic search and recommendation systems. For US teams we self-host inside your VPC for HIPAA and SOC 2 control; for EU clients we keep vectors and payloads in-region for GDPR data residency. From collection schema to distributed sharding, we own the whole vector layer.
Choosing the right vector size, distance metric and HNSW parameters (m, ef_construct, ef) up front, since poor index config quietly caps recall and latency later.
Combining payload filters with similarity search without falling off the HNSW index or paying a full-scan penalty on selective queries.
Cutting RAM and infrastructure cost with scalar or binary quantisation while keeping recall inside acceptable bounds for your use case.
Sizing shards, replication factor and consistency as collections grow into hundreds of millions of points without losing query throughput.
Deciding between operating your own cluster and Qdrant Cloud, then running upgrades, snapshots and monitoring reliably either way.
Keeping vectors in step with changing source data and rotating embedding models without stale results or silent index drift.
We design collections and tune HNSW and search parameters against your recall and latency targets, validated with a real evaluation set.
We combine dense vectors with sparse and keyword signals plus payload filters, so results stay relevant and correctly scoped.
We apply scalar or binary quantisation and oversampling to slash memory and cost while measuring the recall trade-off explicitly.
We configure sharding, replication and consistency for high-volume collections, with capacity planning for steady growth.
We deploy on Docker or Kubernetes in your VPC, or on Qdrant Cloud, with snapshots, monitoring and upgrade runbooks.
We wire Qdrant into a FastAPI retrieval service with re-ranking, embedding pipelines and versioning for production RAG.
GDPR · self-host data residency · HIPAA-ready · SOC 2
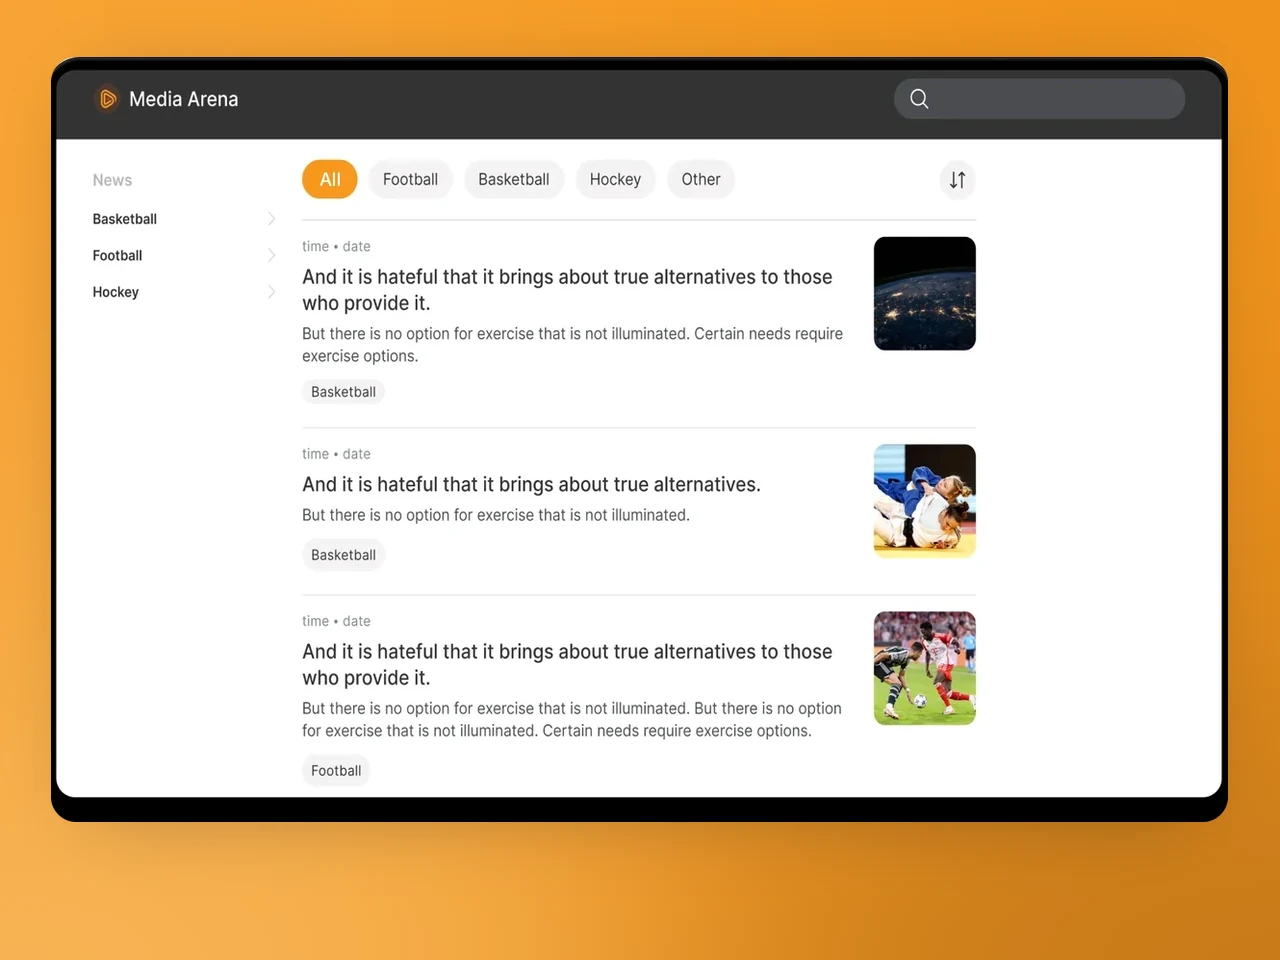
Cross-platform sports news app and web portal — Telegram-bot CMS instead of a custom admin, Markdown publishing pipeline.
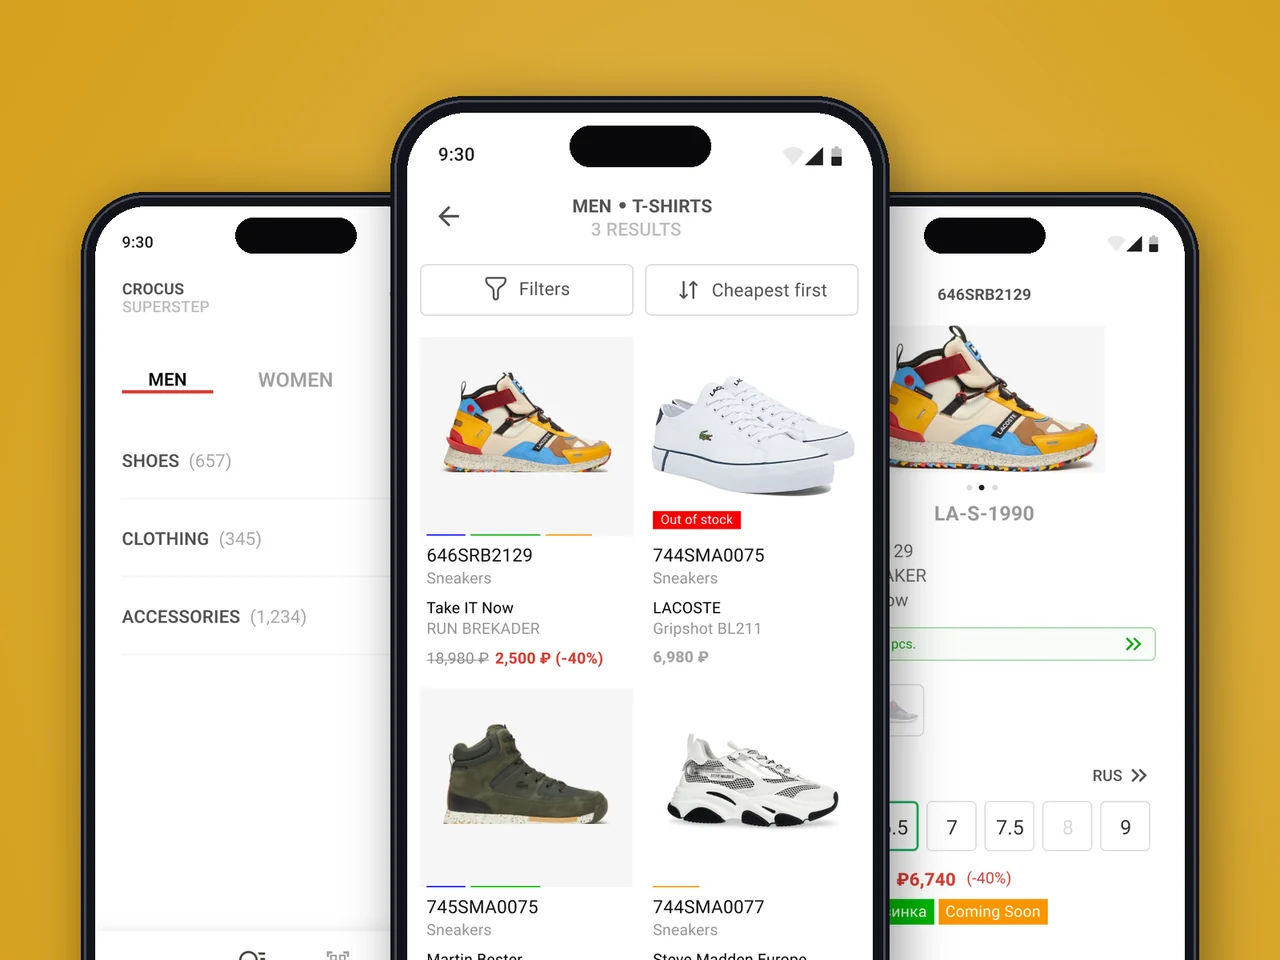
Retail POS companion app for a multi-brand boutique chain — ElasticSearch cross-store inventory search, 1C-system integration.
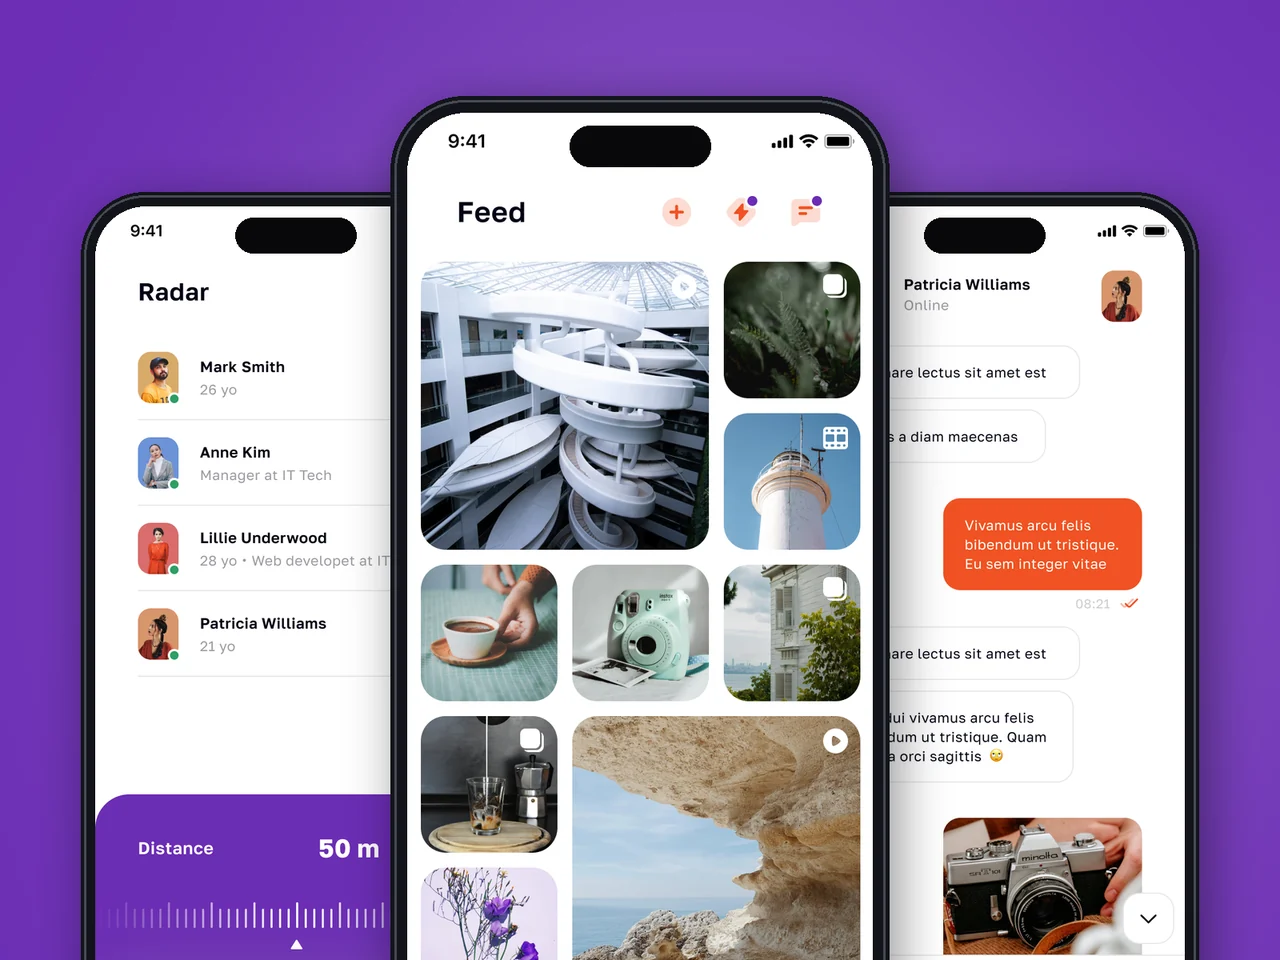
Production social platform — App Store + Google Play, live across the US and EU — with geo Radar, encrypted messaging and a virtual economy.
We publish dozens of sports articles a day. YuSMP built an editorial pipeline using a Telegram bot as the CMS — editors post once, content lands on web, iOS, and Android instantly. The architecture requires zero daily maintenance.
Building a social platform from scratch is high-stakes work. YuSMP delivered the interest feed, geo Radar, Stories, and virtual coins economy on schedule, with a codebase our in-house team picked up on day one of handoff.
Our consultants were losing 15 minutes per customer on manual inventory checks. YuSMP built native apps backed by ElasticSearch, wired to our 1C system in real time. Time-per-customer dropped 40% across all locations within a week of launch.
A loan decision engine that takes ten times less time to approve does not happen by accident. YuSMP built the scoring pipeline, integration with credit bureaus, and a back-office that our underwriters actually enjoy using. Approval turnaround went from two days to under four hours.
1 / 4
We default to self-hosting Qdrant inside your VPC or EU region, so HIPAA, SOC 2 and GDPR data-residency requirements are met by architecture, not bolted on afterwards.
Every index, filter and quantisation decision is backed by a recall-and-latency evaluation harness, so you ship retrieval quality you can prove.
From collection schema to distributed cluster ops and the RAG service on top, one senior team owns the whole retrieval stack end to end.
FAQ
Qdrant is a purpose-built, open-source vector database with strong payload filtering, quantisation and hybrid search, and it runs self-hosted or as Qdrant Cloud. pgvector is simplest when your data already lives in Postgres and scale is modest; Pinecone is fully managed but proprietary and US-hosted; Weaviate is a capable open-source peer. We pick Qdrant when you want open-source control, in-region self-hosting and fine-grained filtered search at scale.
Self-host inside your VPC when you need HIPAA, strict data residency or full infrastructure control; we run it on Docker or Kubernetes with snapshots and monitoring. Qdrant Cloud is the faster path when you want a managed cluster and your compliance posture allows it. We help you choose and can migrate either direction later.
We set m, ef_construct and the query-time ef against your target recall and latency, using a representative evaluation set rather than defaults. We also tune segment and indexing thresholds, and re-test whenever data volume or query patterns change materially.
Scalar quantisation typically cuts memory roughly fourfold and binary quantisation far more, which lowers infrastructure cost and speeds search. The trade-off is some recall loss, which we offset with oversampling and rescoring and always measure explicitly before recommending a setting.
Yes. Qdrant applies payload filters during vector search with a filterable index, so selective metadata queries stay fast instead of degrading to full scans. We also combine dense and sparse vectors for hybrid search, then optionally re-rank, to get both semantic and keyword relevance.
Qdrant scales horizontally through sharding and replication in a distributed cluster. We size shard count, replication factor and consistency for your point count and throughput, plan capacity for growth, and load-test before launch so latency holds as the collection grows.
Self-hosting Qdrant in your EU region keeps vectors and payloads inside your jurisdiction, satisfying data residency. Because every point carries an addressable id and payload, we can delete or update specific records to honour right-to-erasure and rectification requests, and we document the deletion workflow for your DPO.
Tell us where you want to be in twelve months. We’ll come back with a plan to get you there.
Response within 1 business day. NDA on request.
Share a few details and a senior consultant will reply within one business day.
Email: sales@yusmpgroup.com
Phone: +374 44 871 811
Offices: KAMAR Business Center, Vazgen Sargsyan St. 2, Yerevan, Armenia · Remote — East-Coast US overlap (9 AM–1 PM ET)