Schema design & data modelling
Choosing embed versus reference is the decision that defines a MongoDB project. Get it wrong and you face fan-out reads, oversized documents or chatty joins that the document model was meant to avoid.
We build and tune MongoDB systems for product teams across the US and EU — from first schema to multi-region Atlas clusters. Our engineers model documents the right way, write aggregation pipelines that hold up under load, and shard before growth becomes a fire drill. Whether you are launching on Atlas or running self-hosted replica sets, we deliver databases that stay fast and predictable.
We build and tune MongoDB systems for product teams across the US and EU — from first schema to multi-region Atlas clusters. Our engineers model documents the right way, write aggregation pipelines that hold up under load, and shard before growth becomes a fire drill. Whether you are launching on Atlas or running self-hosted replica sets, we deliver databases that stay fast and predictable.
Choosing embed versus reference is the decision that defines a MongoDB project. Get it wrong and you face fan-out reads, oversized documents or chatty joins that the document model was meant to avoid.
Arrays that grow forever — comments, events, line items — push documents toward the 16 MB limit and wreck write performance. Many teams only notice once production slows down.
Without the right compound and partial indexes, queries silently fall back to collection scans. Over-indexing is just as costly, bloating writes and RAM working set.
A poor shard key creates hot shards, uneven distribution and queries that scatter-gather across the cluster. Shard keys are hard to change later, so the choice has to be right early.
Multi-document transactions exist but carry overhead and contention. Teams coming from relational systems often over-use them instead of modelling for atomic single-document writes.
US and EU clients need PHI and personal data encrypted at the field level and pinned to the right region — without breaking queries or the developer experience.
We model collections around your real access patterns, deciding embed versus reference per relationship and bounding arrays with the outlier or bucket pattern so documents stay healthy.
We build aggregation pipelines for reporting, search and analytics — staged, indexed and explained so they run on the server instead of dragging data into the app tier.
We provision Atlas with right-sized replica sets, shard clusters where needed, automated backups, alerting and region pinning, all as repeatable infrastructure.
We use Change Streams to drive real-time features — live dashboards, event propagation, cache invalidation and search-index sync — without brittle polling.
We profile slow queries with explain plans, design compound and partial indexes, and tune the working set so latency stays flat as data grows.
We migrate from relational stores or evolve existing MongoDB schemas safely, with versioned documents and online backfills that avoid downtime.
GDPR · HIPAA-ready · field-level encryption · SOC 2
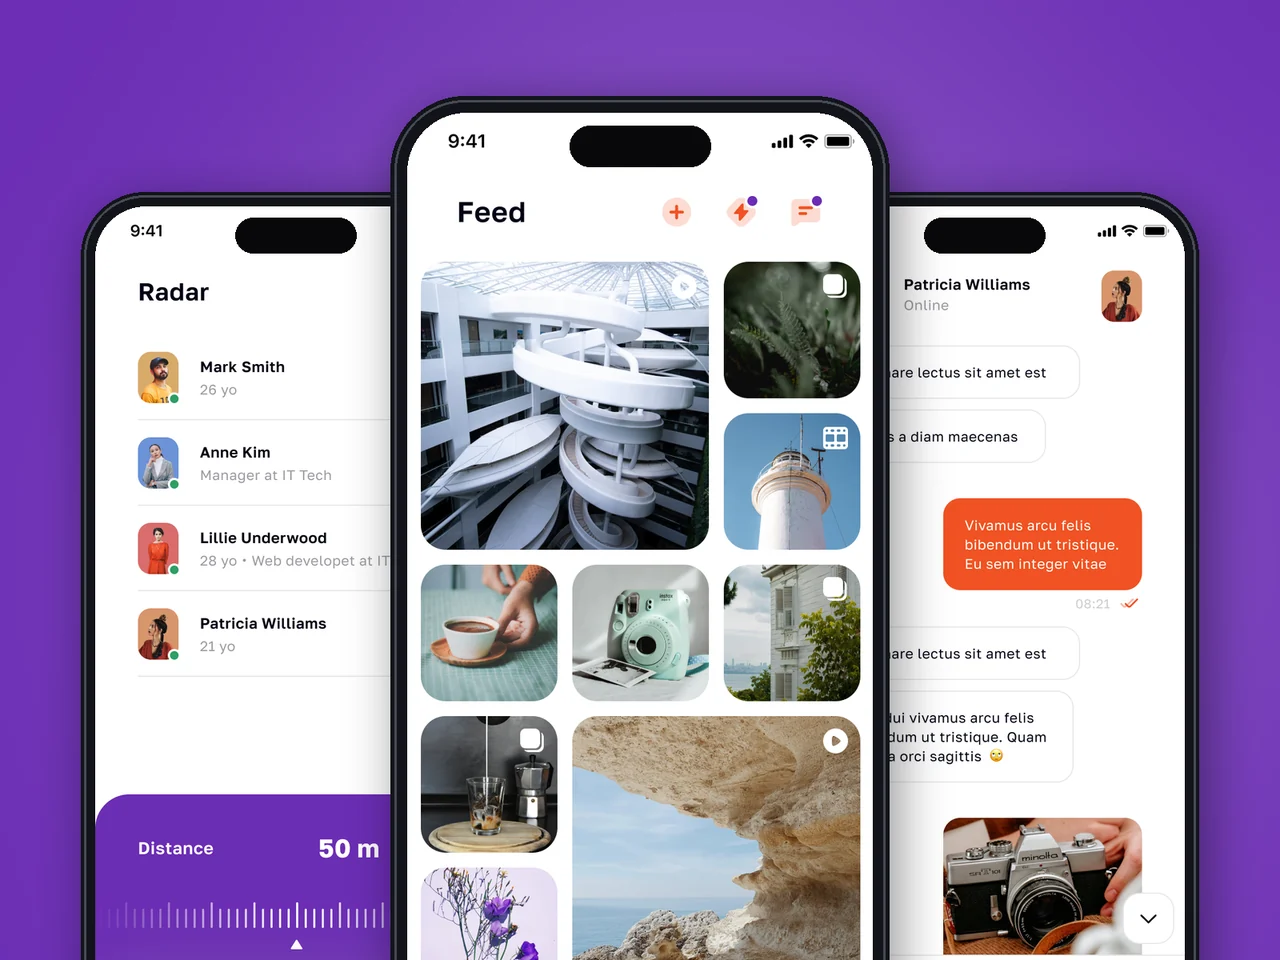
Production social platform — App Store + Google Play, live across the US and EU — with geo Radar, encrypted messaging and a virtual economy.
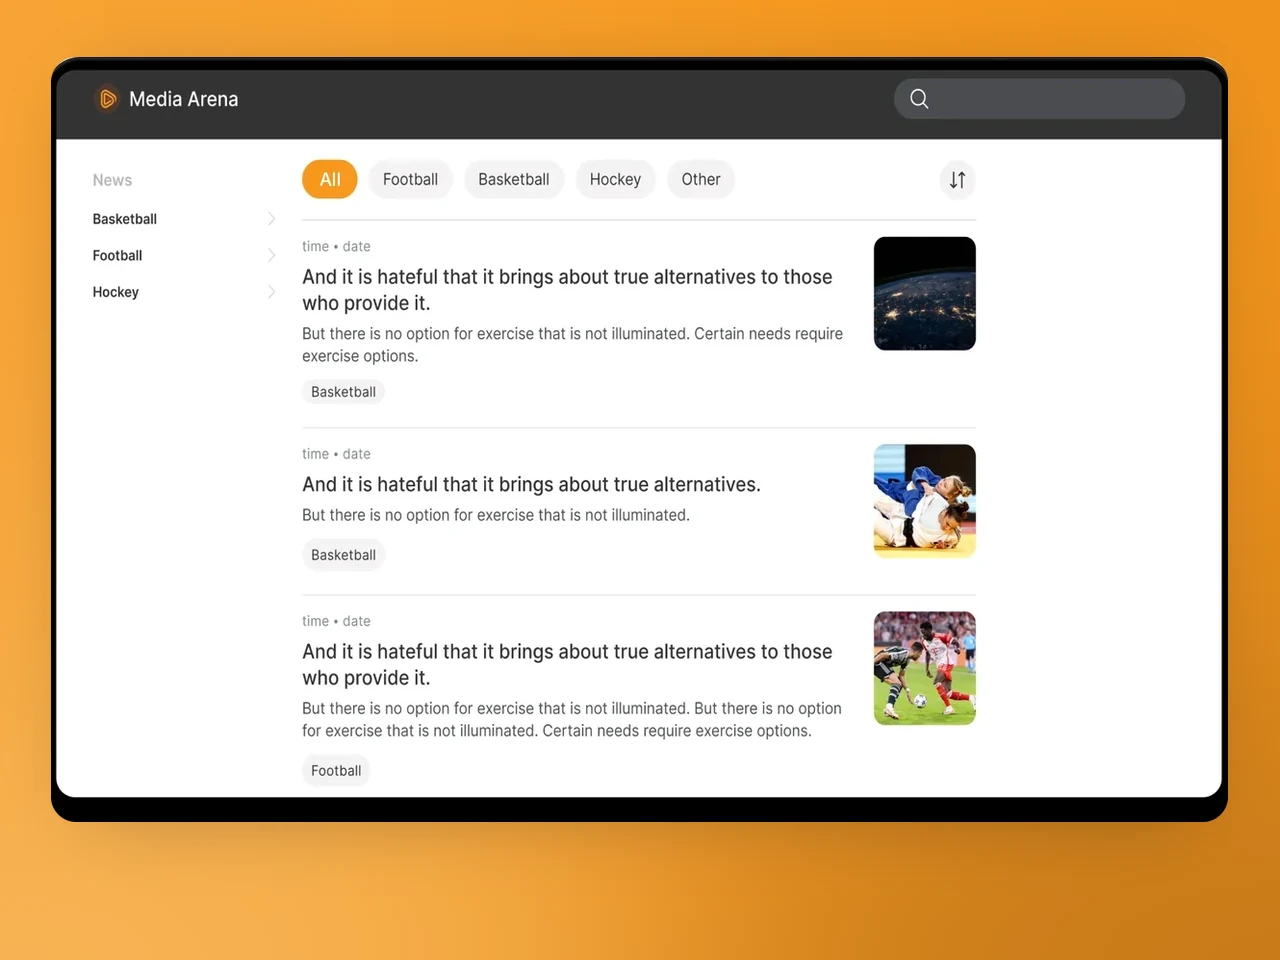
Cross-platform sports news app and web portal — Telegram-bot CMS instead of a custom admin, Markdown publishing pipeline.
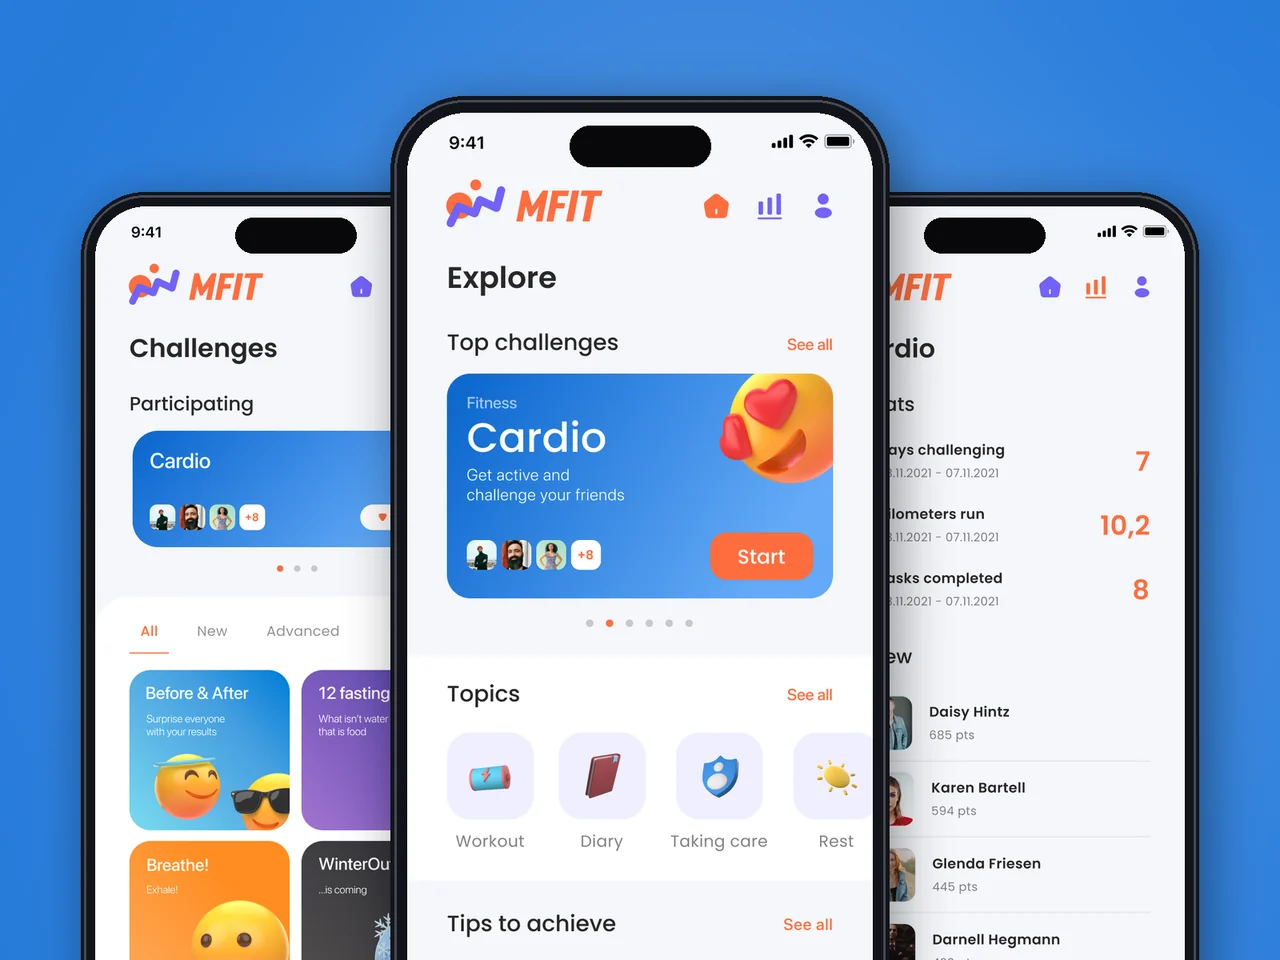
Native iOS & Android fitness-marathon and challenge app — programs, stats, and leaderboards on a Laravel backend, for the US & EU.
We publish dozens of sports articles a day. YuSMP built an editorial pipeline using a Telegram bot as the CMS — editors post once, content lands on web, iOS, and Android instantly. The architecture requires zero daily maintenance.
Building a social platform from scratch is high-stakes work. YuSMP delivered the interest feed, geo Radar, Stories, and virtual coins economy on schedule, with a codebase our in-house team picked up on day one of handoff.
A loan decision engine that takes ten times less time to approve does not happen by accident. YuSMP built the scoring pipeline, integration with credit bureaus, and a back-office that our underwriters actually enjoy using. Approval turnaround went from two days to under four hours.
Telecom self-service is only useful if customers actually prefer it to calling support. YuSMP built iOS and Android apps with balance management, plan switching, and usage analytics that cut our call centre volume by 30% in the first quarter post-launch.
1 / 4
We work in your time zone and to your regulatory reality — GDPR and EU residency for European products, HIPAA and SOC 2 for US ones.
Our engineers live in the aggregation framework, Atlas and sharding internals daily, so you skip the expensive learning curve and the rookie modelling mistakes.
We design schemas and indexes with growth in mind, so your database does not need a rescue project the moment traffic arrives.
FAQ
MongoDB fits when your data is naturally document-shaped, evolves quickly, or comes in flexible structures — product catalogues, user profiles, content, event logs. Relational databases still win for heavy multi-table joins and strict relational integrity. We are happy to advise honestly; sometimes the right answer is both, used for different parts of the system.
The document model shines when you read and write data together as a unit — an order with its line items, a profile with its settings. If your access patterns mostly fetch a coherent object at once, documents reduce round trips and joins. If you constantly query data in many different cross-cutting combinations, we model carefully or reconsider.
Embed when the related data is owned by the parent, bounded in size and usually read together. Reference when it is shared, grows without limit, or is queried independently. We make this decision per relationship based on your real read and write patterns, not as a blanket rule — it is the single most important MongoDB design choice.
Atlas is our default for most teams: managed backups, scaling, monitoring, region pinning and a BAA for HIPAA, with far less operational burden. Self-hosting makes sense when you have strict infrastructure constraints or an existing platform team. We deliver either and can migrate between them.
Yes — MongoDB supports ACID multi-document transactions across replica sets and sharded clusters. That said, the best designs keep most operations within a single document so they are atomic by nature. We use multi-document transactions where they genuinely add value, without leaning on them as a crutch.
You scale reads with replica sets and scale writes and storage horizontally with sharding, which partitions data across nodes by a shard key. The shard key choice is critical — a good one spreads load evenly, a poor one creates hot spots. We choose it deliberately and plan for it early, since it is hard to change later.
Yes. We use Client-Side Field Level Encryption so sensitive fields are encrypted before they ever reach the database, combined with encryption at rest and in transit. Atlas offers a signed BAA for HIPAA workloads, and we pin data to the correct US or EU region for residency requirements.
Tell us where you want to be in twelve months. We’ll come back with a plan to get you there.
Response within 1 business day. NDA on request.
Share a few details and a senior consultant will reply within one business day.
Email: sales@yusmpgroup.com
Phone: +374 44 871 811
Offices: KAMAR Business Center, Vazgen Sargsyan St. 2, Yerevan, Armenia · Remote — East-Coast US overlap (9 AM–1 PM ET)